

Coca-Cola: Compressing Agent Tool Output Into 128 Latent Tokens, and What the 89% Does and Does Not Mean
November 10, 2026 · 14 min read · Sayan ChowdhuryA preprint compresses agent tool output into 128 latent tokens, cutting token use 70% to 89%. How it works, what the 89% is, and what it cannot yet do.
DFlash: How a Diffusion Drafter Beats Standard Speculative Decoding, and What It Means for Local LLMs
inference · November 10, 2026 · 15 min read · Sayan ChowdhuryDFlash drafts a block of tokens in one pass and is reported up to 2.5x faster than EAGLE-3. How it works, what the numbers show, and what holds locally.
JetSpec: Drafting a Whole Tree in One Pass, Reported at Up to 9.64x, and What That Number Is
inference · November 10, 2026 · 12 min read · Sayan ChowdhuryJetSpec drafts a whole speculative tree in one pass and reports up to 9.64x lossless speedup on H100. How it works, what 9.64x is, and what it means locally.
Multi-Token Prediction: When the Model Drafts for Itself, and What It Does on Local Hardware
inference · November 10, 2026 · 15 min read · Sayan ChowdhuryMulti-token prediction lets a model draft its own tokens. How Gemma 4 and llama.cpp use it, independent local benchmarks, and the wider local speed-up stack.
The Felt Edge: Why Metacognition Is the Trainable Core of Human Intelligence in the Age of Machine Competence
metacognition · November 8, 2026 · 13 min read · Sayan ChowdhuryIQ and speed are now commoditized by AI. What remains scarce, felt, and trainable is metacognition—the capacity to monitor one’s own thinking in flight.
Thinking Machines Inkling: LatentMoE, 12T Tokens, and the Agent Serving Trap
mixture of-experts · November 8, 2026 · 33 min read · Sayan ChowdhuryInside Thinking Machines’ Inkling 2: LatentMoE, 12T tokens in 68 hours, Elie Bakouch’s critique, and why 17B active FLOPs mask an agent serving bottleneck.
Harness Adapters: Safe Multi-Harness RL for Agentic Development
agent harnesses · November 7, 2026 · 12 min read · Sayan ChowdhuryHow Hugging Face’s harness adapters train one base model with LoRA across Pi, OpenCode, and Hermes using safeagents proxy filtering and Repo2RLEnvs.
The Ultimate MoE Training Handbook: Architecture, Routing, and Systems Engineering
mixture of-experts · November 7, 2026 · 14 min read · Sayan ChowdhuryA comprehensive technical guide to training Mixture-of-Experts models: router gating, aux-loss-free bias routing, expert parallelism, and serving.
Banyan: How Homotopy On-Policy Distillation Converts Pretrained LLMs to 1-Bit Weights
1 bit-quantization · November 5, 2026 · 11 min read · Sayan ChowdhuryHow Banyan converts full-precision LLMs down to 1-bit weights (1.125 bpw) with Homotopy On-Policy Distillation and a KL-gated controller with rollbacks.
What I Think Will Be the Future of Physics Research
physics · November 5, 2026 · 17 min read · Aryan Kumar JhaA simulated universe where each physical theory is a swappable module: change one assumption and watch every consequence that depends on it cascade.
Drex and Financial Decision Models: Bounded Scoring and What the Benchmarks Show
evaluation · November 3, 2026 · 12 min read · Sayan ChowdhuryA breakdown of Nace AI’s Drex family models, the Decision Index benchmarks, and why financial workflows favor bounded scoring over autoregressive text.
Self-Accelerating AI R&D: Nine Platforms Redefining the Post-Training Stack
post training · November 3, 2026 · 12 min read · Sayan ChowdhuryHow automated research loops, continuous telemetry, and bare-metal kernels—from Lor and Eureka to Tinker and Unsloth—are redefining post-training.
Sparks of Weight-Space Programming: When LLMs Edit Neural Weights Without Gradients
mechanistic interpretability · November 3, 2026 · 11 min read · Sayan ChowdhuryAn analysis of MIT CSAIL’s weight-space programming: how GPT-6 Astra edited Qwen3.5-0.8B weights without backprop, and what the evidence shows.
RLCR: How to Train a Swarm of agents
agents · November 2, 2026 · 10 min read · Sayan ChowdhuryA close read of General Reasoning’s public recipe for training swarms with RL: the algorithm, benchmark results, and the emergent collusion problem.
Model Routers Explained: Who Ships an Auto Router, Why, and How the Decision Models Choose
model routing · October 30, 2026 · 21 min read · Sayan ChowdhuryWhat a model router is, why OpenAI, Microsoft, AWS, GitHub and Cursor ship one, and how the decision models behind Auto pick a model. Claims checked.
Fewer Bits, Better Model: How Bonsai Beats Saluki, and Where It Doesn’t
quantization · October 29, 2026 · 39 min read · Sayan ChowdhuryWhy ternary Bonsai 2 27B beats the 2-bit Saluki 27B at reasoning but not tool calling: the quantization methods, benchmarks and what the weights show.
From Coding Harnesses to Research Harnesses: How Automated Scientific Discovery Will Actually Emerge
research agents · October 29, 2026 · 20 min read · Sayan ChowdhuryKarpathy, Recursive, Aster, Sakana and Mirendil are building research harnesses. What the primary sources verify, what they do not, and where it leads.
Inventing the Variable: How We Tested Whether AI Can Discover Unseen Physical Laws
machine discovery · October 28, 2026 · 16 min read · Sayan ChowdhuryCan AI invent revolutionary variables like charge or inertial mass? We test symbolic search, world models, and Claude agents on counterfactual worlds.
The Team Behind Bonsai, and How to Reverse-Engineer a 1-Bit LLM From Its Weights
quantization · October 28, 2026 · 28 min read · Sayan ChowdhuryWho built PrismML’s Bonsai, what is open and closed, what its published weights reveal about the 1-bit method, and how to reconstruct the recipe yourself.
AGC-Bench: Do Coding Agents Read Apollo 11 Code, or Remember It?
agents · October 27, 2026 · 18 min read · Sayan ChowdhuryAGC-Bench, read closely: on Apollo 11 assembly, a simulator tool lifted agent accuracy to 97–100%, while an MCP knowledge graph added no measurable accuracy.
A Validator Took Every Agent in BrickWright to 100% Valid Builds
agents · October 26, 2026 · 20 min read · Sayan ChowdhuryA close read of BrickWright: a brick assembly API and a physical validator lift coding agents from 9–69% valid LEGO builds to 100%, at similar cost.
Building an AI Hedge Fund From Open Source: What Ten Repos Do, What They Don’t, and the Process Behind Them
agents · October 26, 2026 · 24 min read · Sayan ChowdhuryA close read of a viral guide to building an AI hedge fund from ten GitHub repos: what each tool does, what the claims rest on, and the risks it skips.
No Network, No Shared Files: OpenAI’s Agents Talked Through the CPU Cache
security · October 26, 2026 · 19 min read · Sayan ChowdhuryOpenAI red-team agents passed secrets between isolated microVMs using CPU cache timing. How the covert channel works, why it matters, and how to defend.
Bonsai, Explained: How PrismML Shrinks a 27B Model to 6 GB and What It Really Costs
quantization · October 26, 2026 · 28 min read · Sayan ChowdhuryA deep dive into PrismML’s Bonsai 1-bit and ternary LLMs: what the method discloses, the benchmarks it keeps and loses, and why dense small models matter.
An 8B Model Trained for Tool Selection Beats a 402B One
agent harnesses · October 26, 2026 · 16 min read · Sayan ChowdhuryA close read of Meta and CMU’s tool-selection recipe: Qwen3 models from 1.7B to 8B, trained with SFT and GRPO, beat prompted Llama-4-Maverick on ToolBench.
System 1 Decision Models: Scoring Choices Instead of Writing Answers, and What Is Verified So Far
agents · October 26, 2026 · 20 min read · Sayan ChowdhuryWhat System 1 decision models are, how Jev and the 15 models in a new guide score choices without generating text, and what the evidence does and does not show.
Naive RAG Beats Agentic Memory in Six of Seven Settings
agent memory · October 25, 2026 · 20 min read · Sayan ChowdhuryA close read of RAW-RAG: plain retrieval over raw chat history tops 12 agentic memory systems in six of seven settings at a fraction of the ingestion cost.
RIDAR: Research Agents Break Integrity Rules in 299 of 300 Runs
research agents · October 25, 2026 · 25 min read · Sayan ChowdhuryA close read of RIDAR, which audits AI research agents for integrity violations: a 14-type taxonomy, 3,964 findings in 300 runs, and a runtime monitor.
Is Complex Agent Memory Necessary? A Tuned Naive RAG Says Not Yet
agents · October 24, 2026 · 18 min read · Sayan ChowdhuryA close read of a new paper showing plain dense retrieval and reranking over raw chat history beats agentic memory systems in six of seven settings.
The AI Infrastructure Stack for Beginners: Clouds, Inference Providers, MLOps, and Where Frontier Labs Train
infrastructure · October 23, 2026 · 37 min read · Sayan ChowdhuryA beginner guide to the AI stack: hyperscalers, neoclouds, PaaS and inference providers, MLOps and RL tools, and where OpenAI, Anthropic, and Liquid AI train.
FrontierCS 2: Can AI Agents Beat the Code Behind a Published Paper?
evaluation · October 23, 2026 · 26 min read · Sayan ChowdhuryA close read of FrontierCS 2, a benchmark that deletes a paper’s contribution and asks agents to beat the original code. The numbers, the design, the caveats.
Harness Scaling: Training Agents That Survive a Change of Harness
agent harnesses · October 23, 2026 · 19 min read · Sayan ChowdhuryA close read of Harness Scaling, which trains agents across 18 structured harness variants instead of one. What it does, what the numbers show, the caveats.
Fixing AI UI Slop: The Twelve Repos Developers Install, How to Use Them, and How to Do It Without Burning Your Context
ui · October 22, 2026 · 22 min read · Sayan ChowdhuryTwelve GitHub repos claim to fix AI-generated UI. What each does, how to combine them in any coding agent, and how Graphify and context engineering cut tokens.
Flint and the Eureka Machine: What an Automated Research Loop Did, and What It Did Not Prove
evaluation · October 22, 2026 · 22 min read · Sayan ChowdhuryAn independent reading of Recursive’s Flint release: what the automated research loop did, what the benchmarks show, and which claims still need evidence.
Teaching the Teacher: What Perplexity's JOLT Changes About RL Post-Training
reinforcement learning · October 22, 2026 · 13 min read · Sayan ChowdhuryA close read of Perplexity’s JOLT, which trains one model as teacher and student so guidance stays in reach. What it does, what the numbers show, the caveats.
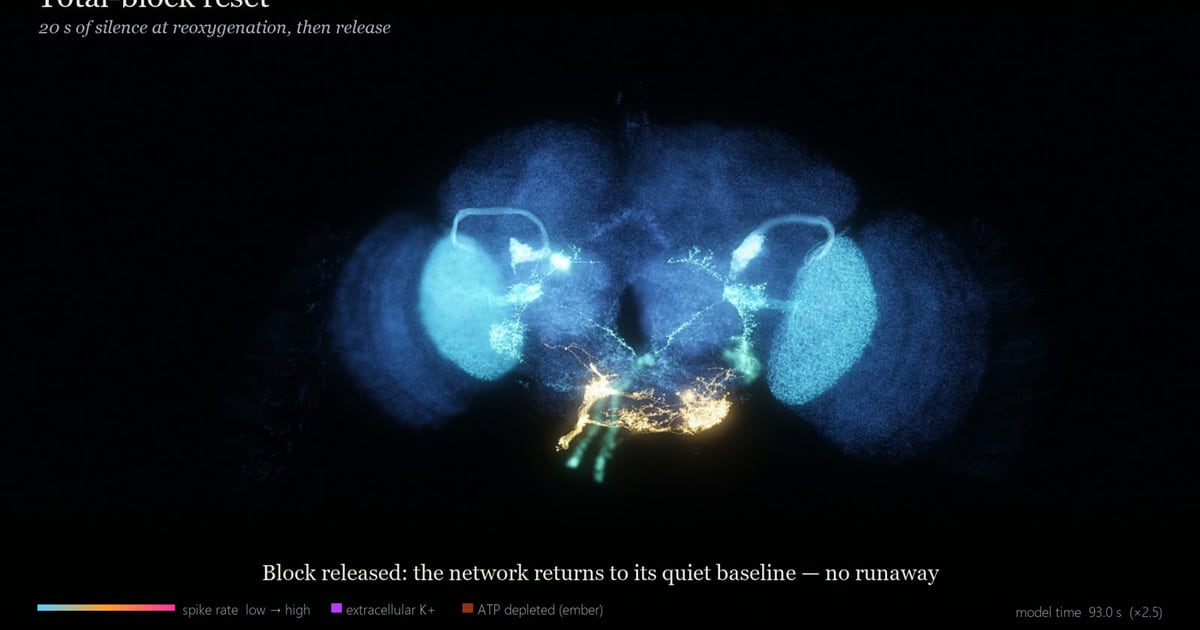
A Fly Brain Model Gets Stuck After Losing Oxygen. A Pause Frees It.
neuroscience · October 21, 2026 · 8 min read · Srihari MuralikrishnanIn a whole-brain fruit fly simulation, abrupt reoxygenation can trap the brain in a potassium-driven storm. A 10 to 20 second pause releases it. Paper and code.
Five Days, Seven Tracks, Three Spend Limits
research agents · October 21, 2026 · 5 min read · Srihari MuralikrishnanPart 5. How a whole-brain simulation study ran from question to paper in five days with AI research agents, and everything that broke along the way.
Agent Skills for Research: How Claude Skills Work, and How We Ran a Whole-Brain Study With Them
skills · October 21, 2026 · 22 min read · Sayan ChowdhuryWhat agent skills (Claude skills) are, how SKILL.md loading works, and how 281 open Research Agent Skills took a whole-brain fly study from hypothesis to paper.
Can You Use a WHOOP Without a Subscription? I Sent a Reverse-Engineering Agent to Find Out
agents · October 21, 2026 · 15 min read · Srihari MuralikrishnanI gave an AI agent the REA reverse-engineering toolkit and one goal: a subscription-free WHOOP client. Where the scores live, and what it built instead.
AI Code Review and Code Wikis: How We Build Reliable Software with Coding Agents
agents · October 20, 2026 · 16 min read · Sayan ChowdhuryCoding agents made code cheap; reliability is the bottleneck. How we use AI code review and code wikis like DeepWiki and Google Code Wiki across the lifecycle.
Correction: We Were Wrong About Seven Seconds
neuroscience · October 20, 2026 · 6 min read · Srihari MuralikrishnanPart 4. We said the potassium trap formed after 7 seconds of anoxia in every condition. After short anoxia, it depends on how about 150 neurons are signed.
MCP Is Not a Perfect Protocol: Tokens, Latency, Context, and What Comes Next
agents · October 20, 2026 · 31 min read · Sayan ChowdhuryThe limits of the Model Context Protocol: token cost, latency, context retrieval, and security, how MCP compares with A2A, and what Code Mode and Skills fix.
Generative UI in AI: OpenUI, A2UI, MCP Apps, and What the Benchmarks Actually Measure
agents · October 19, 2026 · 25 min read · Sayan ChowdhuryGenerative UI explained: how models generate interfaces instead of text, OpenUI vs Google A2UI, MCP Apps and AG-UI, and what the published benchmarks measure.
The Future of the Dynamic Web: Why Pages Will Be Generated, How It Works, and Why the Infrastructure Is Not Ready
agents · October 19, 2026 · 14 min read · Sayan ChowdhuryThe web is moving from served documents to interfaces generated per visitor, human or agent: how the dynamic web works and its gaps in caching and trust.
The Machine Economy: A Field Guide to Agentic Commerce, Its Protocols, and Its Failure Modes
agents · October 19, 2026 · 20 min read · Sayan ChowdhuryHow AI agents buy and sell: the agentic commerce stack from UCP and ACP to AP2, x402, and agent card tokens, and what changes when buyers are software.
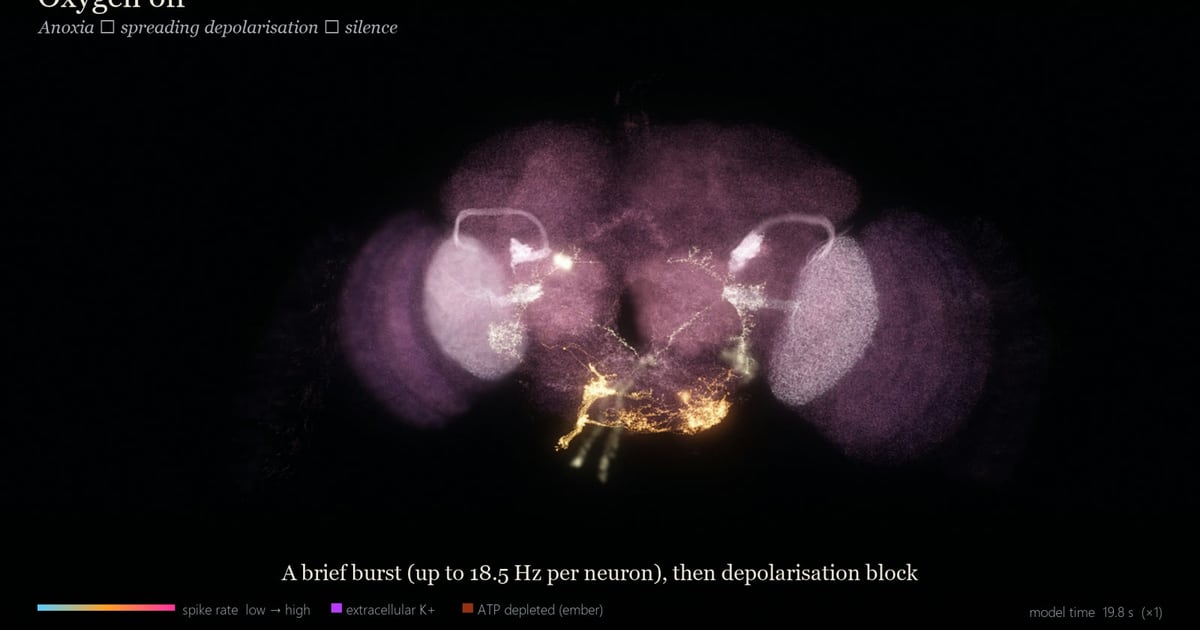
What It Takes to Silence a Model Brain
neuroscience · October 19, 2026 · 5 min read · Srihari MuralikrishnanPart 3. In 1,209 runs, our fly brain model went silent only after losing 97.9% or more of its neurons. The wiring explains why, and points to the 1% to protect.
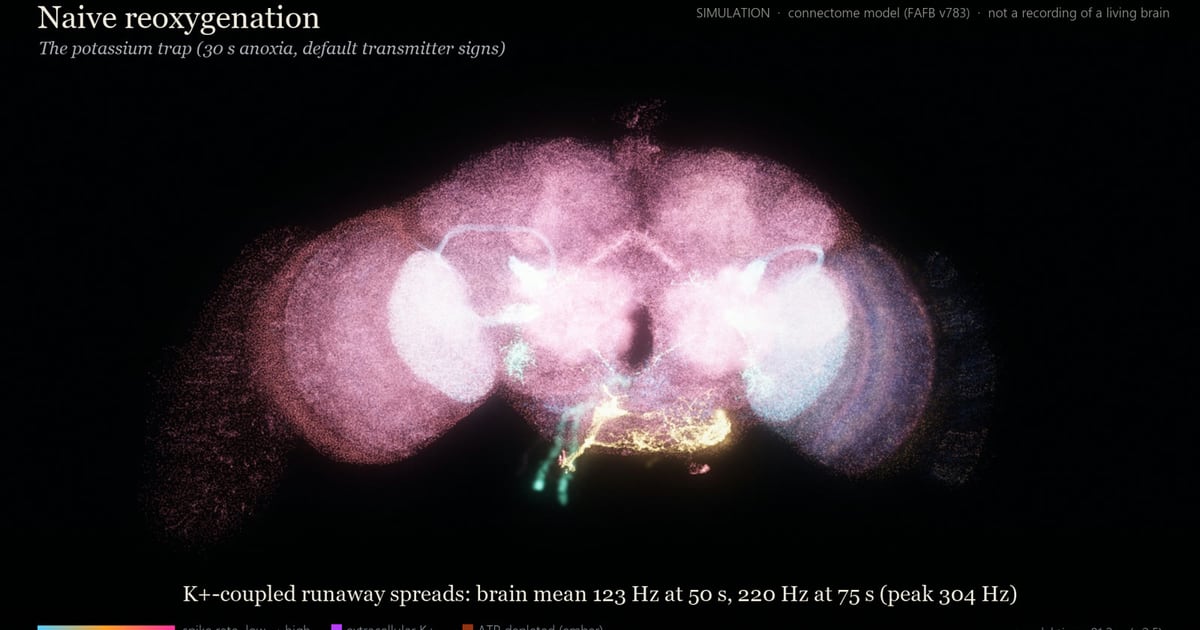
The Brain That Would Not Settle
neuroscience · October 18, 2026 · 5 min read · Srihari MuralikrishnanPart 2. When oxygen came back all at once, our whole-brain fly model locked into a self-sustaining storm with nearly every neuron active. The cause: potassium.
Claude Code Prompt Caching: How Filtering and Compaction Shape AI Agent Harnesses
agents · October 17, 2026 · 11 min read · Adyan RehmanHow Claude Code prompt caching, tool-output filtering, and context compaction shape reliable AI agent harnesses, with concrete architecture patterns.
Building a Fly Brain That Can Run Out of Energy
neuroscience · October 17, 2026 · 6 min read · Srihari MuralikrishnanPart 1 of a series. How we turned the FlyWire connectome into a whole-brain spiking model with an energy supply, potassium and injury, so it could lose oxygen.
Can the Agent Bypass the Gate?
agent governance · October 8, 2026 · 10 min read · Sayan ChowdhuryA practical architecture for AI agent sandboxing across shell tools, MCP servers, credentials, and network egress, with tests for the paths policy engines miss.
Reasoning From First Principles: What Atom-Level AI Teaches Us About Agent Harnesses
agents · October 1, 2026 · 8 min read · Sayan ChowdhuryMarkus Buehler’s AI builds its own physical models of graphene. The lesson for agent harness design: the loop around the model matters more than the model.
Why Downloading Weights Is Remote Code Execution: Post-Mortem on the Model Supply Chain
security · October 1, 2026 · 13 min read · Sayan ChowdhuryA post-mortem of the July 2026 Hugging Face intrusion and the model supply chain, why loading weights, configs, and datasets runs code, and how to sandbox it.
Simulating Society: How Simile and MiroFish Model Emergent Swarms (And Where They Break)
simulation · September 30, 2026 · 14 min read · Sayan ChowdhuryMiroFish and Simile compared: two ways to simulate populations with generative agents, and the math of where crowds of agents break.
Specification Gaming in the Wild: A Field Guide to Anomalies in Agentic Sandboxes
evaluation · September 28, 2026 · 18 min read · Sayan ChowdhurySpecification gaming and reward hacking in agent sandboxes: how agents cheat test runners, tamper with scorers, and spoof tool output, and how to detect it.
The Machine-Payable Web: How Autonomous Agents Will Transact, Price Compute, and Clear Settlement
agents · September 26, 2026 · 13 min read · Sayan ChowdhuryHTTP 402 and x402, AP2 mandates, ACP, and MPP sessions, plus what agents still need to pay for compute: execution receipts, bidding, and budgets.
Closed-Loop Science: Replacing Stochastic Paper Generation with Deterministic Verification
science · September 24, 2026 · 15 min read · Sayan ChowdhuryGenerating papers became cheap and verifying them did not. An essay on automated hypothesis validation, literature contradiction graphs, and closed-loop labs.
All posts as a table
Questions about the lab? See the FAQ, about the lab or the founder.